


10 Free AI Tools That Replace Expensive Software for Data Scientists
Build a production-grade data science toolkit without spending a dollar, using open-source AI tools that match, and sometimes exceed, their paid alternatives.
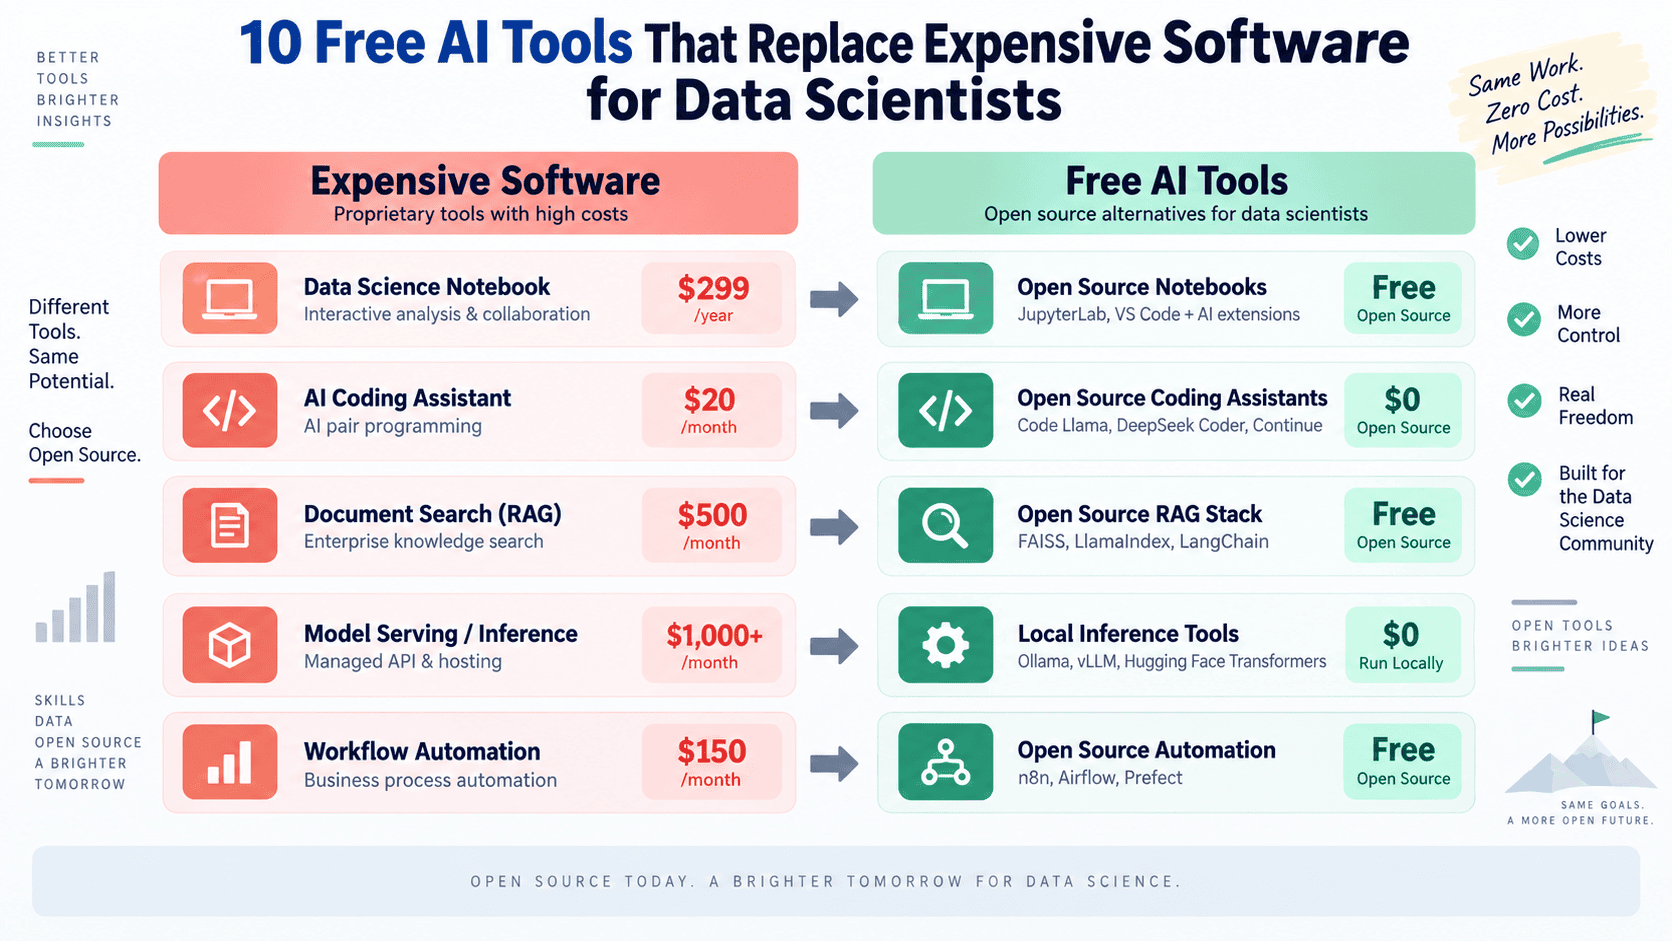
Enterprise data science stacks are expensive. A single DataRobot seat can run over \$50,000 a year. Tableau Creator costs around \$900 per user annually. Commercial large language model (LLM) APIs charge per token, so a team running continuous data extraction or summarization pipelines can rack up thousands of dollars in monthly inference fees with no ceiling in sight.
What's changed recently is the quality and maturity of open-source alternatives. The gap between paid enterprise tools and their free counterparts has narrowed dramatically — for most professional workflows, it's effectively closed. Tools that once required cloud infrastructure and commercial licenses now run locally, perform at state-of-the-art levels, and in several cases do things their paid equivalents can't.
This article covers ten free tools, each mapped to a specific expensive software category, and explains what makes each one a credible replacement. The selection spans the full data science workflow: local inference, AI-assisted coding, automated machine learning (AutoML), natural language data exploration, retrieval-augmented generation (RAG), dataset annotation, visual analytics, experiment tracking, local analytics, and LLM observability.
1. Replacing OpenAI and Anthropic APIs with Ollama + Open WebUI
What it costs to replace: Per-token API fees that scale without a ceiling, often reaching thousands of dollars monthly for data-intensive teams.
Ollama lets you download and run open-weight language models — including DeepSeek-R1, Llama 3.3, Mistral, and Phi-4 — directly on local hardware. No API keys, no rate limits, and no data leaving your machine. For data scientists running document extraction, text classification, summarization, or synthetic data generation pipelines, cutting out per-token costs means those workloads can run continuously without any budget pressure.
Open WebUI pairs with Ollama to give you a browser-based chat interface that mirrors the ChatGPT and Claude experience, including multi-turn conversations, file uploads, and model switching. Non-technical stakeholders can interact with local models through a familiar interface without any data touching external servers.
The privacy angle goes beyond cost, too. Sensitive datasets, proprietary code, and confidential documents can all be processed through these models without triggering compliance reviews, since nothing leaves the local environment.
2. Replacing GitHub Copilot Business and Tabnine with Tabby
What it costs to replace: GitHub Copilot Business runs \$19 per user per month. Tabnine runs \$59 per user per month.
Tabby is a self-hosted AI coding assistant that provides context-aware code completion inside VS Code, JetBrains IDEs, and Vim/NeoVim. It supports any open-weight model as its backend, runs entirely on local or private infrastructure, and integrates with Ollama for model management.
The distinction that matters for data science teams is data sovereignty. When you use GitHub Copilot, your code and context go to Microsoft's servers for completion. For teams working with proprietary algorithms, client data, or regulated environments, that's a compliance problem. Tabby solves it by keeping the entire completion pipeline inside your infrastructure, with no telemetry or external calls.
Beyond privacy, Tabby supports repository-level context indexing — it can be trained on your own codebase to produce completions that reflect your team's specific patterns, conventions, and internal libraries. That's a level of context depth even paid tools struggle to match at the individual organization level.
3. Replacing DataRobot and H2O Driverless AI with AutoGluon
What it costs to replace: DataRobot and H2O Driverless AI enterprise licenses are typically negotiated, but estimates range from \$50,000 to \$250,000+ annually.
AutoGluon, developed by AWS and released as a fully open-source project, automates the end-to-end machine learning lifecycle across tabular, text, image, and multimodal data. It handles preprocessing, feature engineering, model selection, hyperparameter tuning, and ensemble stacking without you having to intervene at each step.
On standard AutoML benchmarks, AutoGluon consistently ranks at or near the top, often beating manually tuned pipelines. For tabular data specifically, its stacking approach combines gradient boosting, neural networks, and other learners into ensembles that are hard to beat without significant engineering effort.
The practical advantage over paid AutoML platforms is that AutoGluon runs entirely within your Python environment. No uploading data to a cloud platform, no per-row pricing, no dataset size limits beyond local compute. Teams can run aggressive hyperparameter searches, generate multiple model variants, and iterate continuously without watching a billing dashboard.
4. Replacing ThoughtSpot and Alteryx with PandasAI
What it costs to replace: ThoughtSpot pricing starts at \$25–\$50 per user per month. Alteryx Designer licenses run approximately \$5,000 per year.
PandasAI adds a natural language query layer directly on top of standard Pandas DataFrames. Instead of writing filtering, grouping, or plotting code, you describe what you want in plain English and PandasAI translates the request into the appropriate Pandas or Matplotlib operations.
For data scientists, the value shows up most during exploratory data analysis (EDA). Describing a chart or aggregation verbally, then inspecting and tweaking the generated code, is often faster than writing it from scratch, especially for one-off analyses that don't warrant reusable functions.
For non-technical collaborators, PandasAI removes the Python requirement entirely. Analysts and domain experts can interrogate datasets directly, generate their own summaries, and filter data without waiting on engineering support. That self-service capability is the core value proposition of tools like ThoughtSpot, and PandasAI delivers it inside the Jupyter environment teams already use.
PandasAI also supports local models via Ollama, so the natural language layer can run completely offline with no query data sent to external services.
5. Replacing Enterprise RAG Platforms with AnythingLLM
What it costs to replace: Enterprise RAG platforms and internal knowledge base tools range from \$500 to several thousand dollars per month depending on document volume and user count.
AnythingLLM is a full-stack RAG application that turns local files, PDFs, code repositories, websites, and structured data into a queryable AI knowledge base. It runs locally, connects to Ollama for inference, and doesn't need cloud infrastructure or API keys.
Setup is deliberately simple: point AnythingLLM at a folder of documents, and it handles chunking, embedding, vector storage, and retrieval automatically. The resulting interface lets you ask questions against your own data with source citations, so it's easy to verify where answers come from.
For data science teams, the use cases are immediate. Internal documentation, research papers, historical reports, and codebase READMEs can all be ingested and queried conversationally. Teams currently paying for enterprise knowledge management tools or document search platforms can replicate that functionality locally at no cost, while keeping full control over their data.
6. Replacing Scale AI and Labelbox with Autodistill
What it costs to replace: Scale AI and Labelbox charge per labeled item or per seat, with costs for large annotation projects reaching tens of thousands of dollars.
Autodistill uses large foundation models — including Grounding DINO and the Segment Anything Model (SAM) — to automatically generate labels for computer vision (CV) datasets without human annotators. You define the classes you want to detect in natural language, and Autodistill uses zero-shot detection models to label your images accordingly.
The labeled dataset can then train a smaller, faster model optimized for your specific deployment environment, a process Autodistill calls "distillation." The result is a custom object detection model built entirely from unlabeled images, with no manual annotations and no annotation platform subscription.
For teams building CV pipelines, the cost reduction is significant. Projects that would previously require hundreds of hours of human annotation time can be bootstrapped automatically, with human review saved for the cases where the foundation model is uncertain. On common object classes, annotation quality is high enough for most production use cases without manual correction.
7. Replacing Tableau and Power BI Premium with PyGWalker
What it costs to replace: Tableau Creator runs approximately \$75 per user per month. Power BI Premium per user runs \$24 per user per month.
PyGWalker transforms a standard Pandas or Polars DataFrame into an interactive drag-and-drop visual exploration interface directly inside a Jupyter notebook. The interface is modeled on Tableau's shelf-based interaction model: drag fields onto axes, switch chart types, apply filters, and layer dimensions without writing any visualization code.
The key difference from standalone BI tools is that PyGWalker lives inside the analysis environment. There's no export step, no data connection to configure, and no separate application to maintain. Visualizations are created in the same notebook where the data is processed, and the exploration is immediately reproducible.
For teams that use Tableau primarily for EDA and internal reporting rather than published dashboards, PyGWalker covers the use case without the license overhead. Its AI query feature also supports natural language chart generation, which cuts down the friction of switching between analysis and visualization.
8. Replacing Weights and Biases Enterprise with MLflow
What it costs to replace: Weights & Biases Team plans start at \$25 per user per month. Enterprise pricing is negotiated separately and is significantly higher.
MLflow is the open-source standard for machine learning experiment tracking, model registry management, and deployment tooling. It logs parameters, metrics, artifacts, and model versions across training runs, and provides a browser-based UI for comparing experiments, visualizing learning curves, and moving models through staging and production environments.
Where MLflow has gotten stronger recently is LLM support. It now tracks prompt versions, response quality scores, and token usage alongside traditional machine learning metrics, making it a single tracking interface for teams building both predictive models and LLM-based applications.
The self-hosted deployment model means all experiment data stays within your infrastructure, which matters for teams working with sensitive training data. No per-seat cost, no data egress to an external platform, and no features gated behind a higher pricing tier.
9. Replacing Snowflake and BigQuery for Local Analytics with DuckDB
What it costs to replace: Small to mid-sized teams on Snowflake or BigQuery routinely spend \$500 to \$2,000+ monthly on compute and storage for analytics workloads.
DuckDB is an in-process analytical database that runs SQL queries directly against Parquet files, CSV files, JSON, and Pandas DataFrames — without loading data into a server or cloud platform first. For datasets under roughly 100GB, its query performance rivals managed cloud data warehouses, and it runs entirely on local hardware with no infrastructure to configure.
The workflow shift for data scientists is real. Instead of uploading data to Snowflake, writing queries against a cloud warehouse, and paying for compute time, you can query files directly from the filesystem at comparable speeds. DuckDB integrates natively with Pandas and Polars, so results come back as DataFrames and slot directly into existing analysis pipelines.
For teams whose Snowflake or BigQuery usage is primarily exploratory analytics and model feature generation rather than multi-user reporting infrastructure, DuckDB handles that workload at zero cost and with lower latency — there's no network round-trip involved.
10. Replacing LangSmith with Langfuse
What it costs to replace: LangSmith Plus plans start at \$39 per seat. Enterprise plans are negotiated separately.
Langfuse is an open-source LLM observability and evaluation platform. It captures traces of every LLM call in an application — including the prompt, the model response, token counts, latency, and cost estimates — and organizes them into a structured debugging interface. Teams can score outputs, tag failures, run evaluation datasets against prompt versions, and monitor production applications for quality regressions.
For data scientists building LLM pipelines, observability is frequently the missing layer. A pipeline producing inconsistent outputs is hard to debug without visibility into what each model call actually received and returned. Langfuse provides that visibility in a self-hosted environment, with integrations for LangChain, LlamaIndex, and direct API calls.
Langfuse deploys via Docker in a few minutes, so teams can have production-grade LLM monitoring running locally or on private infrastructure without committing to a managed platform or per-trace pricing.
Recommended Learning Resources
Each tool covered here has strong official documentation, and most have active communities on GitHub and Discord. For structured learning alongside these tools, these free resources are worth bookmarking:
- AutoGluon documentation and tutorials (free): Official guides covering tabular, text, multimodal, and time series tasks with worked examples
- MLflow quickstart and concepts guide (free): The official getting-started path covers experiment tracking through model deployment in a single afternoon
- DuckDB documentation (free): Includes a SQL reference, performance tuning guidance, and integration examples for Pandas and Arrow
- Langfuse documentation (free): Covers self-hosted deployment, SDK integration, and evaluation workflows
- Fast.ai Practical Deep Learning (free): Broad coverage of the Python machine learning ecosystem, useful context for several tools on this list
Final Thoughts
The ten tools covered here address the two constraints that most commonly hold data science teams back: cost and data privacy. Running inference, annotation, analytics, and LLM observability locally eliminates both at once. No per-token fees, no per-seat licenses, no sensitive data leaving your infrastructure.
The honest trade-off is configuration time. Paid platforms absorb setup complexity in exchange for subscription fees. Open-source tools put that configuration work back on your plate. For most of the tools here, that overhead is measured in hours, not days, and the long-term savings far outweigh the setup investment.
A practical way to start: identify the single highest line item in your current data science software budget and tackle that one first. Get one replacement running and stable before moving to the next. Within a quarter, a fully open-source stack is achievable without meaningful capability loss.
Vinod Chugani is an AI and data science educator who bridges the gap between emerging AI technologies and practical application for working professionals. His focus areas include agentic AI, machine learning applications, and automation workflows. Through his work as a technical mentor and instructor, Vinod has supported data professionals through skill development and career transitions. He brings analytical expertise from quantitative finance to his hands-on teaching approach. His content emphasizes actionable strategies and frameworks that professionals can apply immediately.